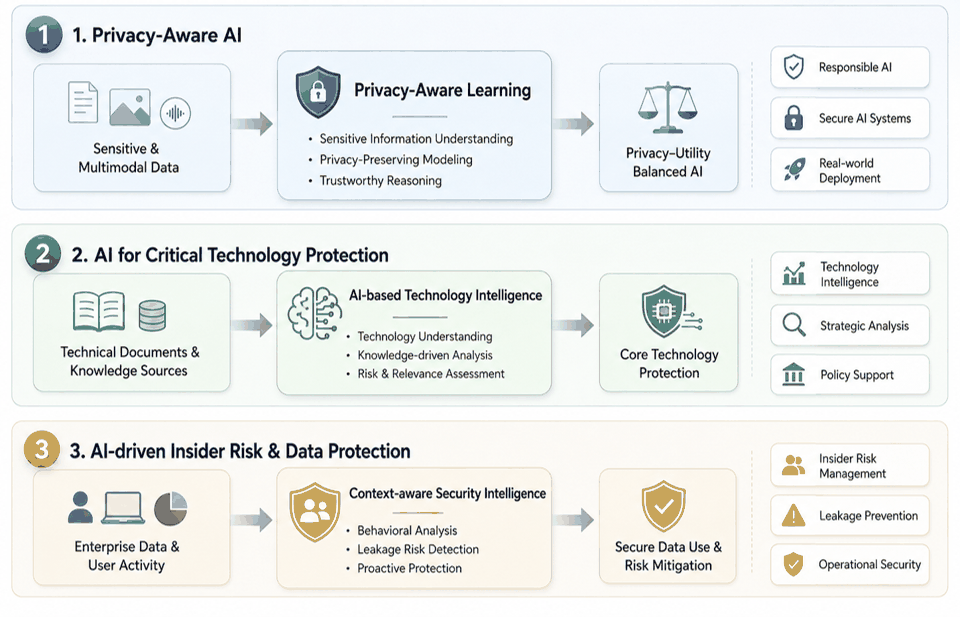
프라이버시 인지형 AIPrivacy-Aware AI
민감정보를 보호하면서 데이터의 의미와 모델 성능을 얼마나 보존할 수 있는가? How much meaning and model performance can we keep while protecting sensitive information?
생성형 AI와 데이터 분석 환경에서 개인정보와 민감정보를 식별하고, 보호 수준에 맞게 비식별화하거나 재현데이터로 변환합니다. 민감정보 이해, 프라이버시 보존형 모델링(PETs), 신뢰할 수 있는 추론을 거쳐 프라이버시와 활용성이 균형을 이루는 AI 모델을 개발하는 것을 목표로 합니다. 단순 마스킹 수준을 넘어 downstream utility와 재식별 위험을 함께 평가합니다. In generative-AI and analytics workflows we identify personal and proprietary technical information, then de-identify it — or replace it with synthetic data — at a level matched to the protection required. Through sensitive-information understanding, privacy-preserving modelling and trustworthy reasoning, the goal is AI that balances privacy against utility. What matters is not masking accuracy alone, but downstream utility and re-identification risk measured together.